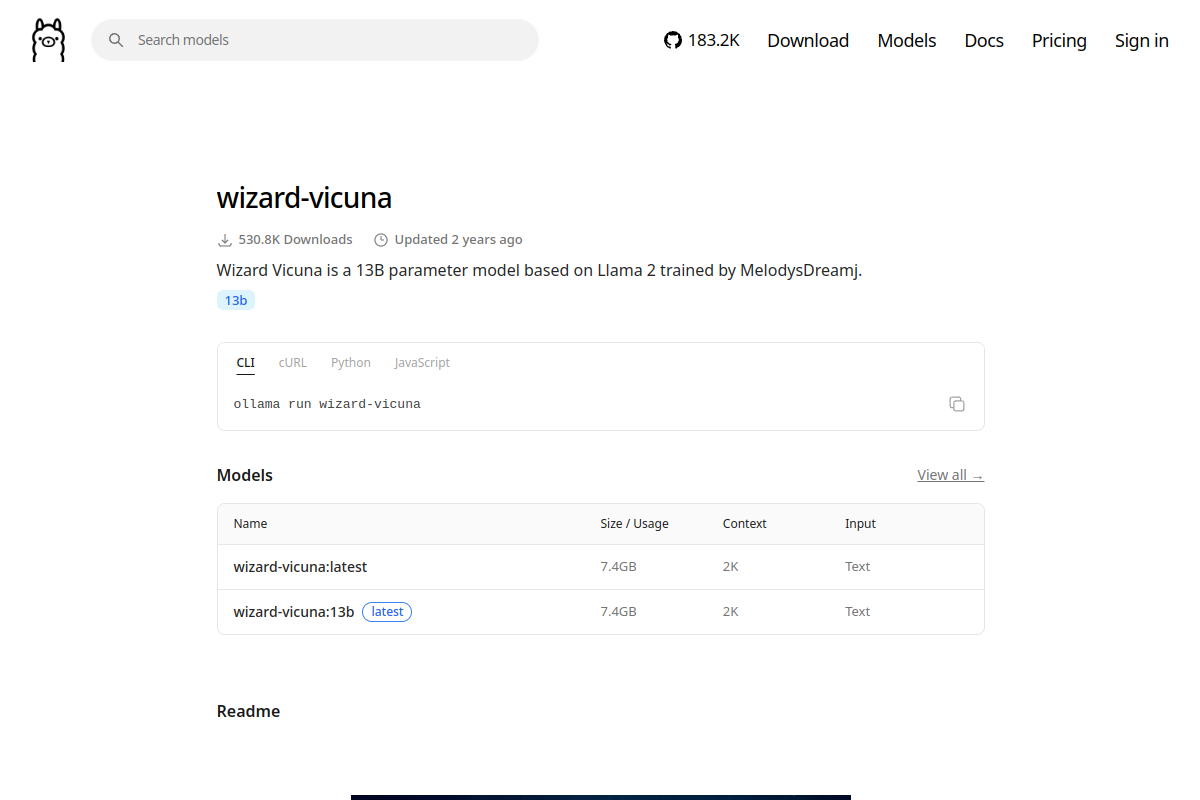
wizard-vicuna
wizard-vicuna is a model entry associated with Ollama. This listing is intended to help developers, researchers, students, and AI application builders discover and organize available language or generative AI models for experimentation, prototyping, model comparison, and software integration. The supplied dataset does not include a model-specific capability description for this record, so capabilities such as reasoning, coding, instruction following, multilingual support, vision or audio processing, tool use, structured outputs, and long-context processing should not be assumed from the model name alone. Before using this model in an application, review the linked provider or model documentation for its architecture or model family, supported modalities, context window, input and output formats, API requirements, licensing terms, pricing or free-tier conditions, rate limits, safety constraints, and current availability. Production deployments should additionally test model quality, latency, reliability, privacy requirements, and workload-specific performance using representative data from the intended application.
Tool Details
Preview
Related Tools
NVIDIA Nemotron 3.5 Content Safety is a compact 4B-parameter multimodal guardrail model from NVIDIA, fine-tuned from Google Gemma-3-4B. It moderates both inputs to and responses from LLMs and VLMs, accepting. NVIDIA: Nemotron 3.5 Content Safety (free) is listed as a large language or generative AI model associated with nvidia, with the model identifier nvidia/nemotron-3.5-content-safety:free. It can be considered by developers, researchers, and AI application builders when evaluating models for programmatic AI workflows, experimentation, prototyping, model comparison, or integration into applications. The supplied description above captures the model-specific capabilities available in this dataset; exact context limits, supported input and output modalities, tool-calling behavior, structured-output support, pricing, rate limits, licensing, deployment options, and availability should be confirmed from the linked provider or model documentation because these technical details can vary between model versions and may change over time. For production use, developers should also evaluate output quality, latency, reliability, safety behavior, privacy requirements, and workload-specific performance against their own application requirements rather than assuming that one model configuration is suitable for every use case.
NVIDIA: Nemotron 3 Ultra (free)
LLM Models
NVIDIA Nemotron 3 Ultra is an open frontier-reasoning and orchestration model from NVIDIA, with 55B active parameters out of 550B total (MoE). Built on a hybrid Transformer-Mamba mixture-of-experts architecture, it. NVIDIA: Nemotron 3 Ultra (free) is listed as a large language or generative AI model associated with nvidia, with the model identifier nvidia/nemotron-3-ultra-550b-a55b:free. It can be considered by developers, researchers, and AI application builders when evaluating models for programmatic AI workflows, experimentation, prototyping, model comparison, or integration into applications. The supplied description above captures the model-specific capabilities available in this dataset; exact context limits, supported input and output modalities, tool-calling behavior, structured-output support, pricing, rate limits, licensing, deployment options, and availability should be confirmed from the linked provider or model documentation because these technical details can vary between model versions and may change over time. For production use, developers should also evaluate output quality, latency, reliability, safety behavior, privacy requirements, and workload-specific performance against their own application requirements rather than assuming that one model configuration is suitable for every use case.
NVIDIA: Nemotron 3 Ultra
LLM Models
NVIDIA Nemotron 3 Ultra is an open frontier-reasoning and orchestration model from NVIDIA, with 55B active parameters out of 550B total (MoE). Built on a hybrid Transformer-Mamba mixture-of-experts architecture, it. NVIDIA: Nemotron 3 Ultra is listed as a large language or generative AI model associated with nvidia, with the model identifier nvidia/nemotron-3-ultra-550b-a55b. It can be considered by developers, researchers, and AI application builders when evaluating models for programmatic AI workflows, experimentation, prototyping, model comparison, or integration into applications. The supplied description above captures the model-specific capabilities available in this dataset; exact context limits, supported input and output modalities, tool-calling behavior, structured-output support, pricing, rate limits, licensing, deployment options, and availability should be confirmed from the linked provider or model documentation because these technical details can vary between model versions and may change over time. For production use, developers should also evaluate output quality, latency, reliability, safety behavior, privacy requirements, and workload-specific performance against their own application requirements rather than assuming that one model configuration is suitable for every use case.